Audio News
Audio-Omni: Extending Multi-modal Understanding to Versatile Audio Generation and Editing
Audio-Omni: Extending Multi-modal Understanding to Versatile Audio Generation and Editing
https://ift.tt/dwrc06p
Recent advances in multimodal models have driven rapid progress in audio understanding, generation, and editing. Yet these capabilities are usually tackled by specialized models, leaving the development of a genuinely unified framework that can seamlessly integrate all three tasks largely underexplored. While a few pioneering works have begun to unify audio understanding and generation, they often stay limited to particular domains. To address this, we present Audio-Omni, the first end-to-end framework to unify generation and editing across general sound, music, and speech domains, with integrated multimodal understanding capabilities. Our architecture combines a frozen Multimodal Large Language Model for high-level reasoning with a trainable Diffusion Transformer for high-fidelity synthesis. To mitigate the critical data scarcity in audio editing, we construct AudioEdit, a new large-scale dataset consisting of over one million carefully curated editing pairs. Extensive experiments show that Audio-Omni achieves state-of-the-art performance across a broad set of benchmarks, surpassing prior unified approaches while matching or exceeding the performance of specialized expert models. Beyond its core capabilities, Audio-Omni exhibits notable inherited capabilities, including knowledge-augmented reasoning generation, in-context generation, and zero-shot cross-lingual control for audio generation, signaling a promising direction toward universal generative audio intelligence. The code, model, and dataset will be publicly released at https://zeyuet.github.io/Audio-Omni.
HI-FI News
via Artificial Intelligence https://ift.tt/OsDap2u
April 14, 2026 at 05:27AM
-
Product on sale
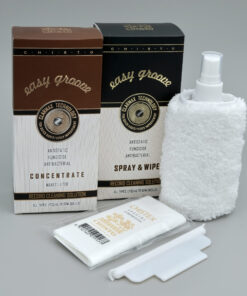
 Audiophile Vinyl Records Cleaning BundleOriginal price was: €69.90.€59.90Current price is: €59.90. excl. VAT
-
Product on saleEasy Start Vinyl Records Cleaning KitOriginal price was: €69.90.€59.90Current price is: €59.90. excl. VAT
-
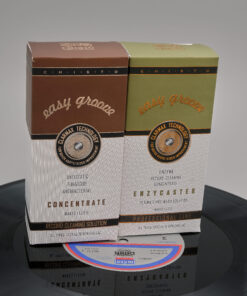
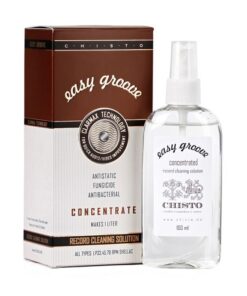
Vinyl Records Cleaner Easy Groove Concentrate€34.95 excl. VAT
-
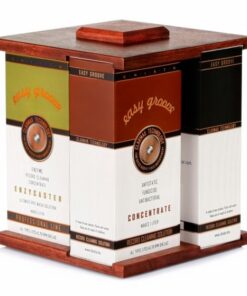
Easy Groove Super Set€199.00 excl. VAT
-
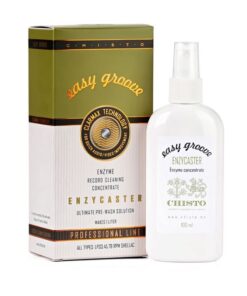
Easy Groove Enzycaster – vinyl records prewash cleaner€34.95 excl. VAT
-
Easy Groove Extreme MK. II- vinyl records prewash cleaner€45.00 excl. VAT
-
Vinyl Records Cleaner – Easy Groove Virgin Concentrate€35.00 excl. VAT
-
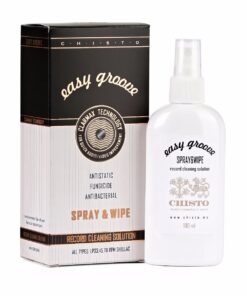
Easy Groove Spray&Wipe vinyl records cleaner€34.95 excl. VAT